Time-Based Data Aggregation
Overview
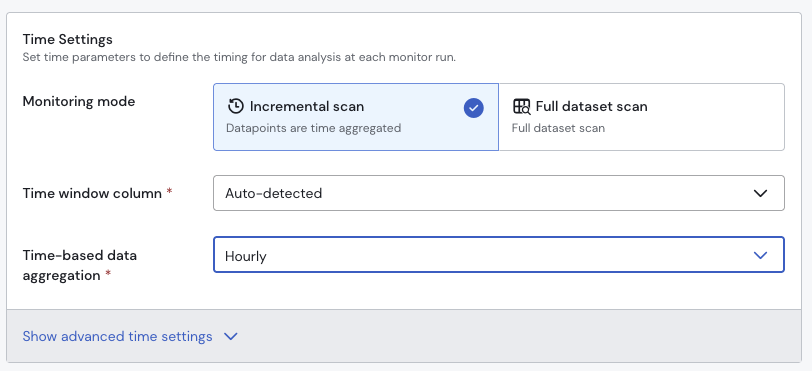
Time-based Data Aggregation is a setting that defines how often data points are created. It can match the monitor run schedule, but it does not have to.
How to Use It
Where to Find It
The Time-based Data Aggregation setting is available in the Monitor Setup. It lets you adjust the data point creation frequency to better match your data monitoring needs.
How Does It Work
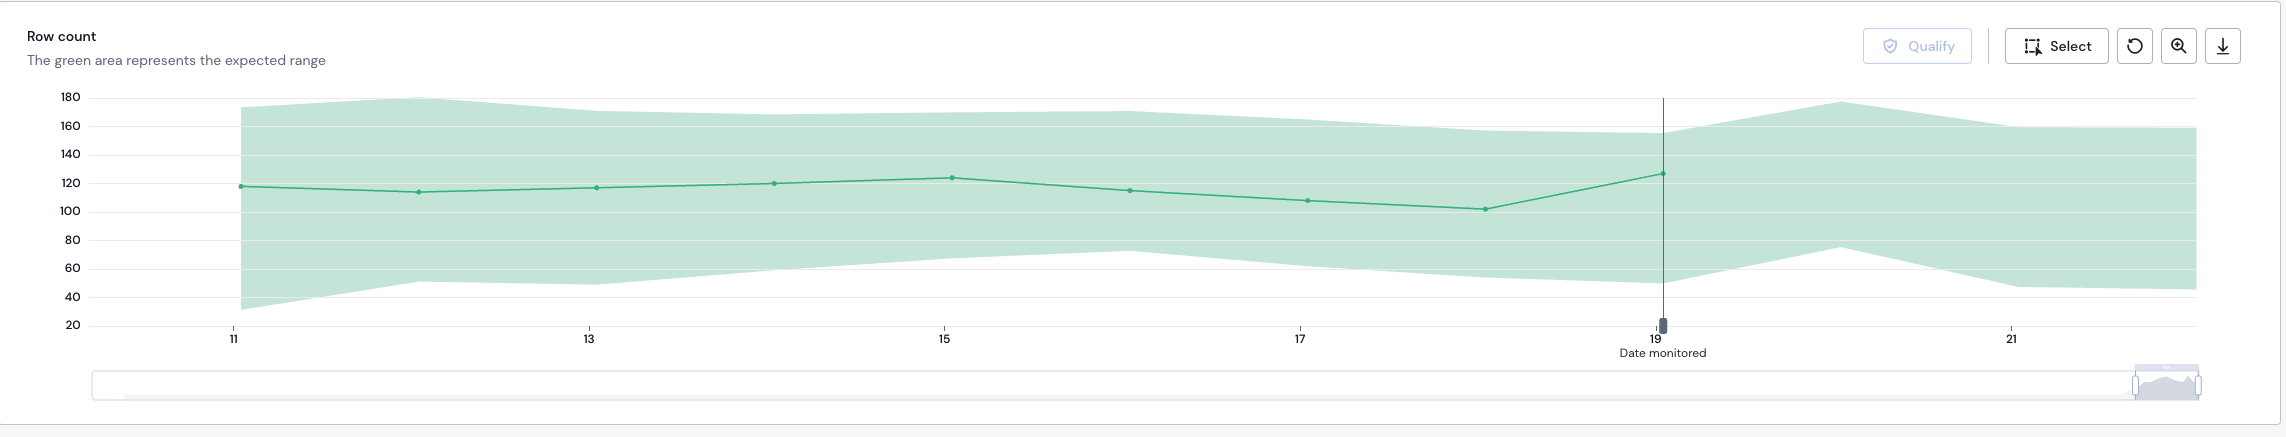
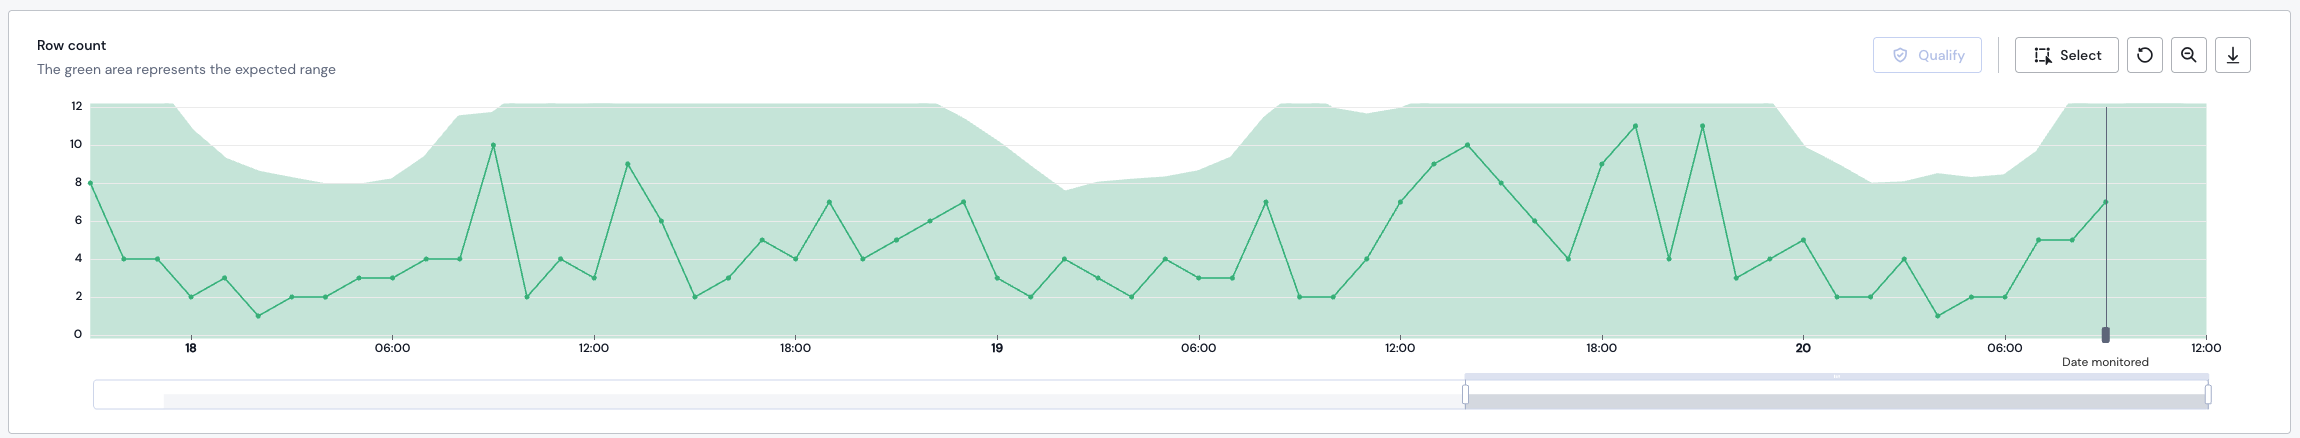
The images below show results of the same monitor run on the same dataset with the same settings. The only difference is the Time-based Data Aggregation parameter — daily and hourly, for the upper and lower images respectively. Notice the improved precision with the same schedule frequency.
Impact on ML Monitors Time Window (Model Training Period)
To keep performance sustainable, Sifflet limits the maximum value of the Time Window (Model Training Period) parameter of machine learning (ML) monitors, depending on the chosen Time-based Data Aggregation setting:
| Time-based Data Aggregation | Time Window (Model Training Period) maximum value |
|---|---|
| monthly | 5 years |
| weekly | 3 years |
| daily | 3 years |
| hourly | 45 days |
| intra-hourly (enterprise-only) | 7 days |
Examples
- Hourly: Suited to monitors that track the evolution of the number of transactions during the day. You get 1 data point per hour, so even if the monitor runs once per day, you can still detect, for example, a lunchtime spike in grocery items.
- Daily: Useful for monitoring a sum of sales during the day. For example, run a monitor on a weekly schedule and create 1 data point per day. This lets you account for differences between particular days of the week.
- Weekly, monthly: Logistics and supply chain scenarios, for example monitoring a relationship between incoming and outgoing packages on a weekly basis.
Updated 1 day ago