BigQuery
Sifflet monitors the health and quality of your BigQuery data, from table updates down to individual field values and business metrics. When an issue occurs, lineage built from your BigQuery job history shows its root cause upstream and the downstream tables and dashboards it affects. Sifflet also catalogs your BigQuery tables and views, with their labels and usage, so you can find what to monitor.
See BigQuery Collected Data for the full list of assets and metadata Sifflet imports.
Permissions Required
Sifflet connects to BigQuery with a dedicated Google Cloud service account that has read-only access to your data and to your BigQuery job history. You grant these permissions through a custom IAM role.
| Permission | Used for | Required |
|---|---|---|
bigquery.datasets.get | List datasets, read their location, and check access with INFORMATION_SCHEMA.SCHEMATA | Yes |
bigquery.tables.list | List the tables and views of each dataset | Yes |
bigquery.tables.get | Read table and view metadata (schema, description, labels, partitioning, view definition) | Yes |
bigquery.tables.getData | Run monitors, data preview, and AI suggestions | Yes |
bigquery.jobs.create | Run metadata queries and monitor queries | Yes, on the billing project (the data project if you don't use a separate billing project) |
bigquery.jobs.listAll | Read INFORMATION_SCHEMA.JOBS_BY_PROJECT and INFORMATION_SCHEMA.JOBS: lineage (including field-level lineage), data usage, and asset update history | Yes (checked by Test Connection) |
bigquery.datasets.get and bigquery.jobs.listAll on each worker project | Lineage and data usage from jobs that run in worker projects | Optional (worker projects) |
| Viewer access to the Cloud Storage buckets, or the Google Drive files and folders, referenced by external tables | Monitor external tables | Optional (external tables) |
Unless you configure worker projects or a billing project, grant all permissions on the project that contains your data. Sifflet doesn't need any write permission: bigquery.jobs.create only lets it run queries, and it never creates, modifies, or deletes tables.
Sifflet can also use the lineage computed by Google Cloud instead of the job history: see BigQuery Lineage with the Data Lineage API.
Cost and load: the queries Sifflet runs during metadata refreshes and monitor runs are billed to the billing project, or to the data project if you don't set one. Set a separate Billing Project ID in the source to track this cost separately. Every monitor query starts with a SQL comment that contains "app": "Sifflet", and Sifflet identifies its API requests with the Sifflet/1.0 (GPN:Sifflet;) user agent.
Requirements
Required Roles for Setup
- In Google Cloud, on the project (and on the billing and worker projects, if any):
- Project IAM Admin (
roles/resourcemanager.projectIamAdmin) - Role Administrator (
roles/iam.roleAdmin) - Service Account Admin (
roles/iam.serviceAccountAdmin) - Service Account Key Admin (
roles/iam.serviceAccountKeyAdmin)
- Project IAM Admin (
- In Sifflet: the Admin system role to create the credential, and the Admin or System Editor role to create the source. See Access Control.
Supported Versions and Editions
- Sifflet imports tables, views, materialized views, and external tables. BigQuery ML models, table snapshots, and external tables on Bigtable aren't supported.
- Sifflet authenticates with a service account key (JSON).
Network Access
- Default: Sifflet connects to the Google Cloud APIs (BigQuery) over the internet.
- IP allowlisting: if your project is protected by a VPC Service Controls perimeter, add an access level that allows the IP addresses of your Sifflet instance, listed in Settings > Integration Preferences.
Other Prerequisites
- The BigQuery API is enabled on the data project and on the billing project.
Connect Sifflet to BigQuery
Step 1: Create a Service Account in Google Cloud
Create a Custom Role
-
In the Google Cloud console, go to IAM & Admin > Roles and click Create role (documentation).
-
Name the role, for example
SiffletRole. -
Click Add permissions and add the following permissions:
bigquery.datasets.get bigquery.jobs.create bigquery.jobs.listAll bigquery.tables.get bigquery.tables.getData bigquery.tables.list -
Click Create.
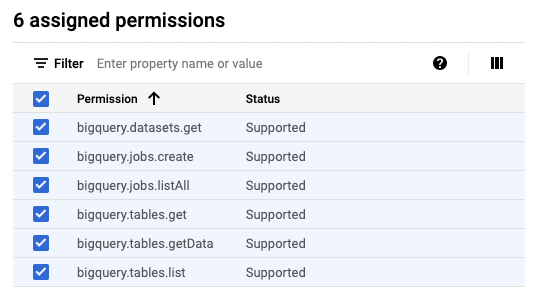
List of permissions that need to be granted to the role
Create the Service Account and Its Key
-
Go to IAM & Admin > Service Accounts and click Create service account (documentation).
-
Name the service account, for example
sifflet. -
In Grant this service account access to project, select the custom role you created (in the Custom section). You can skip Grant users access to this service account.
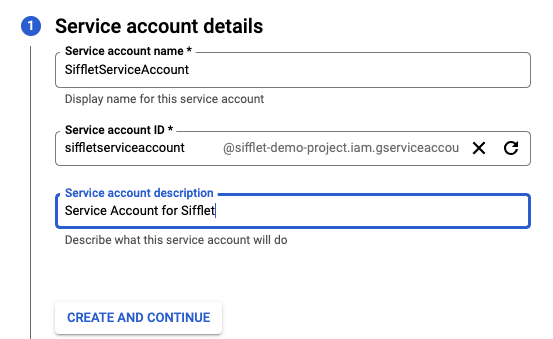
Creating the service account
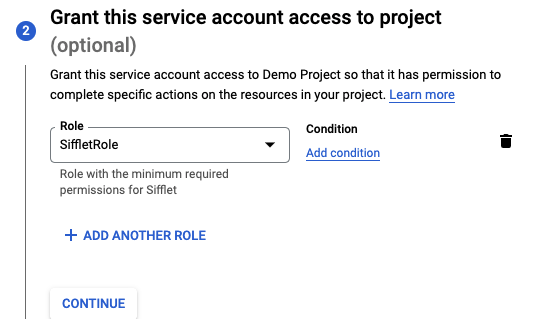
Assigning the custom role to the service account
-
Select the service account, then click Actions > Manage keys.
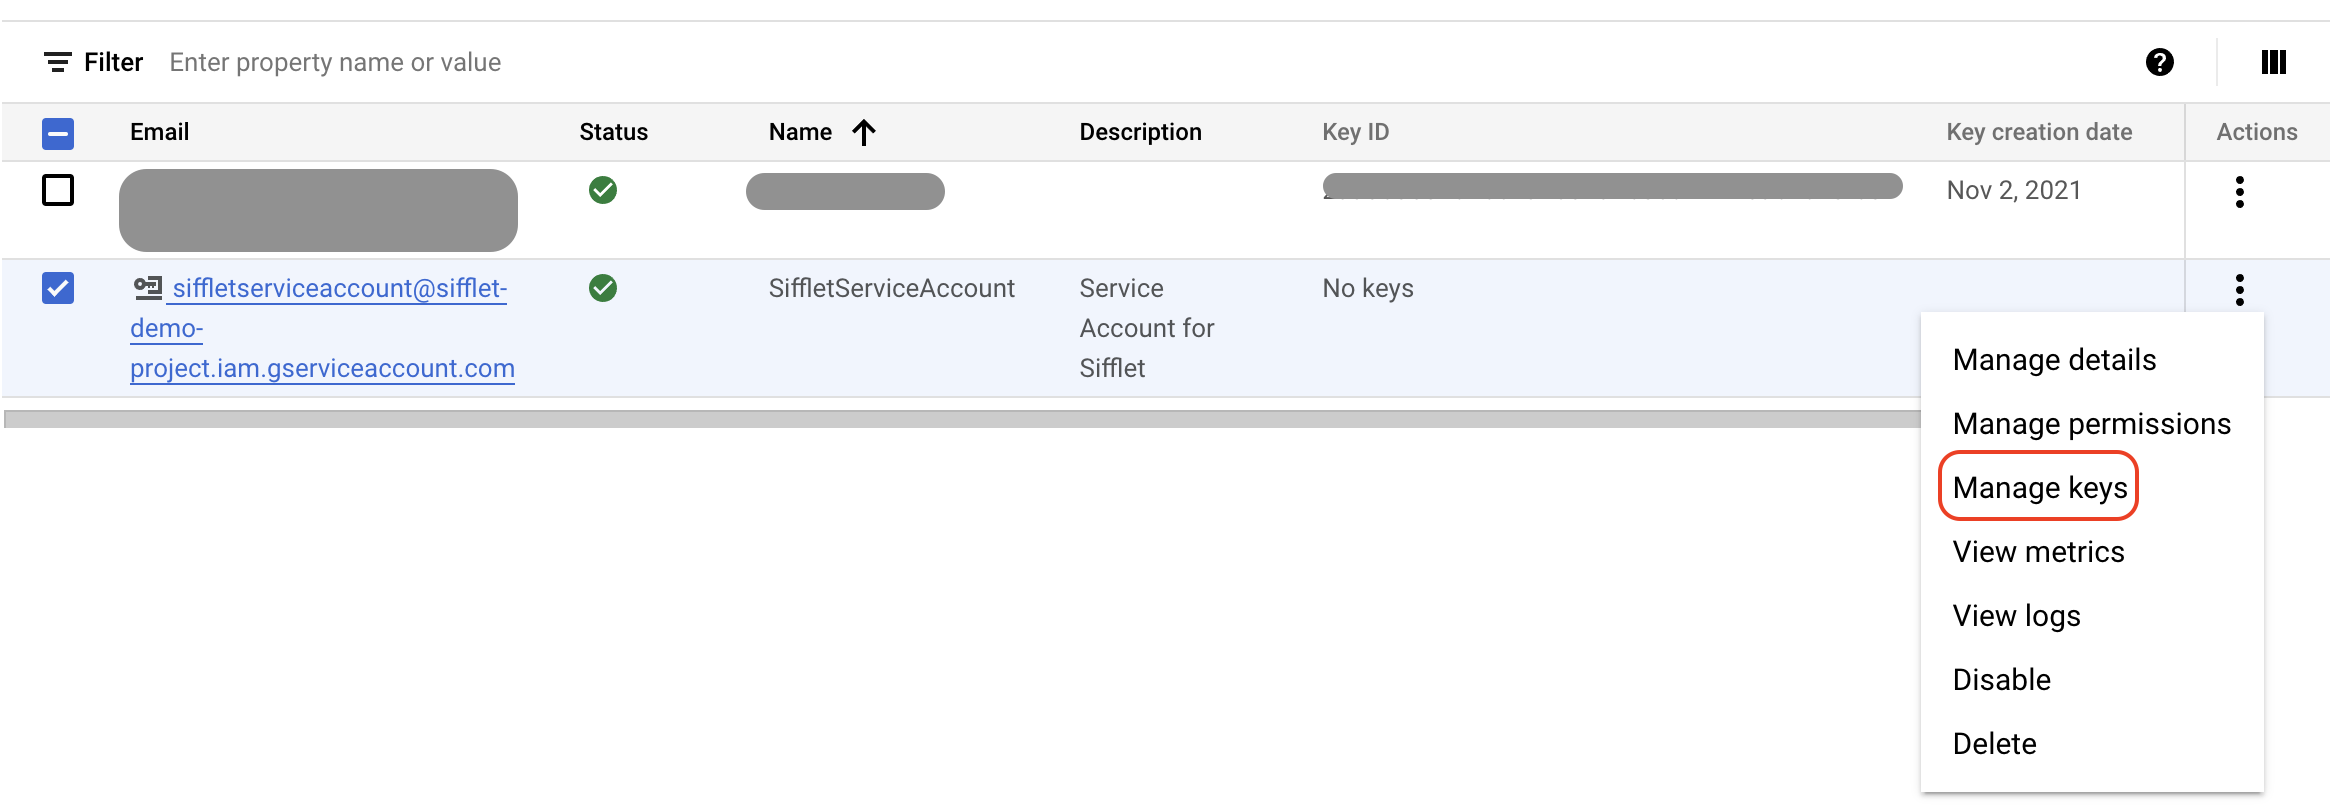
Accessing the key management page
-
Click Add key > Create new key, select JSON, and click Create.
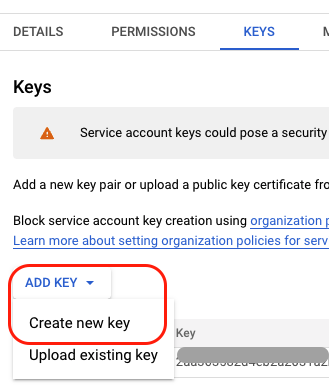
Creating a new key for the service account
-
Keep the downloaded JSON key file for step 2. Google Cloud lets you download it only once: if you lose it, create a new key and delete the old one.
Alternative: Grant Access Dataset by Dataset
To control exactly which datasets Sifflet sees, grant the permissions at dataset level instead of project level:
-
Create a first custom role with only
bigquery.jobs.create, and grant it to the service account on the project (as in the previous procedure). -
Create a second custom role with:
bigquery.datasets.get bigquery.jobs.listAll bigquery.tables.get bigquery.tables.getData bigquery.tables.list -
For each dataset to monitor:
- In the BigQuery Explorer panel, select the dataset.
- Click Sharing > Permissions, then Add principal.
- In New principals, enter the Sifflet service account.
- In Select a role, select the second custom role, and click Save.
bigquery.jobs.listAll is a project-level permission: also grant the second role, or a role with bigquery.jobs.listAll, on the project so that Sifflet can read the job history. With dataset-level grants, Test Connection can show a warning about INFORMATION_SCHEMA.SCHEMATA: you can ignore it if no check fails.
Alternative: Use a Separate Billing Project
To bill Sifflet's queries to another project (an empty one, for instance):
- On the billing project, grant the service account a custom role with
bigquery.jobs.create. - On the data project, grant it a custom role with
bigquery.datasets.get,bigquery.jobs.listAll,bigquery.tables.get,bigquery.tables.getData, andbigquery.tables.list. - In step 2, enter the billing project in Billing Project ID.
Optional: Grant Access to Worker Projects
If you run queries on the data project's tables from other projects ("worker projects"), the job history of these projects contains lineage and usage information. On each worker project, grant the service account a custom role with bigquery.datasets.get and bigquery.jobs.listAll, then list the projects in Worker Project IDs in step 2.
Optional: Grant Access to External Tables
To monitor external tables, the service account also needs read access to their data:
- Cloud Storage: grant the Storage Object Viewer role on the buckets referenced by your external tables, or the
storage.buckets.get,storage.buckets.list,storage.objects.get, andstorage.objects.listpermissions on the project. - Google Drive and Google Sheets: share the files or folders referenced by your external tables with the service account email, with Viewer access.
Step 2: Add the BigQuery Source in Sifflet
Create the Credential
Go to Integrations > Credentials, click New credential, and paste the whole content of the JSON key file in the Credential field. The file looks like this:
{
  "type": "service_account",
  "project_id": "<PROJECT_ID>",
  "private_key_id": "<PRIVATE_KEY_ID>",
  "private_key": "-----BEGIN PRIVATE KEY-----\n<PRIVATE_KEY>\n-----END PRIVATE KEY-----\n",
  "client_email": "<SERVICE_ACCOUNT_NAME>@<PROJECT_ID>.iam.gserviceaccount.com",
  "client_id": "<CLIENT_ID>",
  "auth_uri": "https://accounts.google.com/o/oauth2/auth",
  "token_uri": "https://oauth2.googleapis.com/token",
  "auth_provider_x509_cert_url": "https://www.googleapis.com/oauth2/v1/certs",
  "client_x509_cert_url": "<CLIENT_X509_CERT_URL>"
}
Create the Source
Go to Integrations > Sources, click New source, select BigQuery, and fill in the form:
| Field | Description | Example |
|---|---|---|
| Name | The name of the source in Sifflet | BigQuery production |
| Project ID | The ID (not the name) of the project that contains your datasets, as shown in IAM & Admin > Settings | my-data-project |
| Billing Project ID | Optional. The project to which Sifflet's queries are billed. Defaults to the Project ID | my-billing-project |
| Worker Project IDs | Optional. Comma-separated IDs of the projects whose job history Sifflet reads for lineage and usage, in addition to the Project ID | etl-project,bi-project |
| Credential | The credential created above | bigquery-sifflet-sa |
Select the Scope
Click Load assets to list the datasets that the service account can access in the project, then select the datasets to include in the Data Catalog. Turn on Automatically include new datasets so that Sifflet catalogs datasets created later. Create one source per project, not one per dataset. See Integrations Management for scope, refresh frequency, and scheduling options.
Test and Save
Click Test Connection. For each dataset, Sifflet checks that it can:
- find the dataset in the project's
INFORMATION_SCHEMA.SCHEMATA; - list the dataset's tables and read their data (
bigquery.tables.getandbigquery.tables.getData); - read the dataset location and list the jobs of the project, and of each worker project, in
INFORMATION_SCHEMA.JOBS_BY_PROJECT.
If a check fails, see BigQuery Troubleshooting. Then click Save. Sifflet starts the first metadata refresh right away: you can follow its status and logs from the source details in Integrations > Sources. Assets appear in the Data Catalog once the refresh completes.
Troubleshooting
See BigQuery Troubleshooting for project, credential, and permission errors.
Updated 12 days ago