dbt Core
This page explains how to connect dbt Core to Sifflet: your pipelines send the dbt artifacts to Sifflet after each dbt command. For an overview of the dbt integrations, see dbt, and for the list of imported assets and metadata, see dbt Collected Data.
Permissions Required
The dbt Core integration is push-based: Sifflet never connects to your dbt project or to your runners. Your pipeline uploads the dbt artifacts to the Sifflet API, authenticated with a Sifflet access token.
| Permission | Used for | Required |
|---|---|---|
Sifflet access token with the Editor token role | Upload manifest.json and run_results.json to the Sifflet API, which triggers the ingestion of the dbt Core source | Yes |
Read access to the dbt target/ folder on the machine that runs dbt | Read the artifacts to upload | Yes |
Editor is the least-privileged token role that can upload dbt artifacts: the Viewer role can't. The Admin role also works but grants more than needed.
The integration doesn't run any query on your data platform and has no compute cost.
Requirements
Required Roles for Setup
- In Sifflet: the
Adminsystem role to create the access token, and theAdminorSystem Editorsystem role to create the dbt Core source. See Access Control. - In your pipeline: the rights to add a step after your dbt commands and to store the access token as a secret.
Supported Versions and Editions
- dbt Core, run from any orchestrator or CI tool that can run a shell command, the Sifflet CLI, or the Sifflet Airflow operator.
- The project's dbt adapter (
adapter_typeinmanifest.json) must correspond to a data platform supported by Sifflet. - For dbt Cloud, use the dbt Cloud integration instead, or this integration if you can't adapt your dbt Cloud jobs to the dbt Cloud integration's requirements.
Network Access
The connection goes from your systems to Sifflet: the machine that runs dbt (CI runner, Airflow worker, container) must be able to reach the API of your Sifflet instance over HTTPS: https://<TENANT>.siffletdata.com/api.
Other Prerequisites
- Connect the data platform where dbt builds your models (Snowflake, BigQuery, Databricks, and so on) as a Sifflet source, so that Sifflet can link your dbt models to the monitored tables and views.
- Know the name of your dbt project (
nameindbt_project.yml) and the target used by your pipeline (inprofiles.yml, or the--targetoption). Both are case-sensitive. Create one dbt Core source per project and target pair.
Connect Sifflet to dbt Core
Step 1: Create an Access Token and the dbt Core Source in Sifflet
Create the Access Token
- In Sifflet, create an access token with the
Editorrole, following Access Tokens. - Copy the token: Sifflet shows it only once. Store it in the secrets manager of your orchestrator or CI tool.
Create the dbt Core Source
-
Go to Integrations > Sources > New source and choose dbt Core.
-
Fill in the fields:
Field Description Example Source name Name of the source in Sifflet dbt Core - analytics - prodProject name Name of your dbt project, exactly as in the namekey ofdbt_project.ymlanalyticsTarget Name of the dbt target your pipeline runs with, exactly as in profiles.ymlprodCreate incident when monitor fails When enabled (default), a failing dbt test creates an incident Enabled 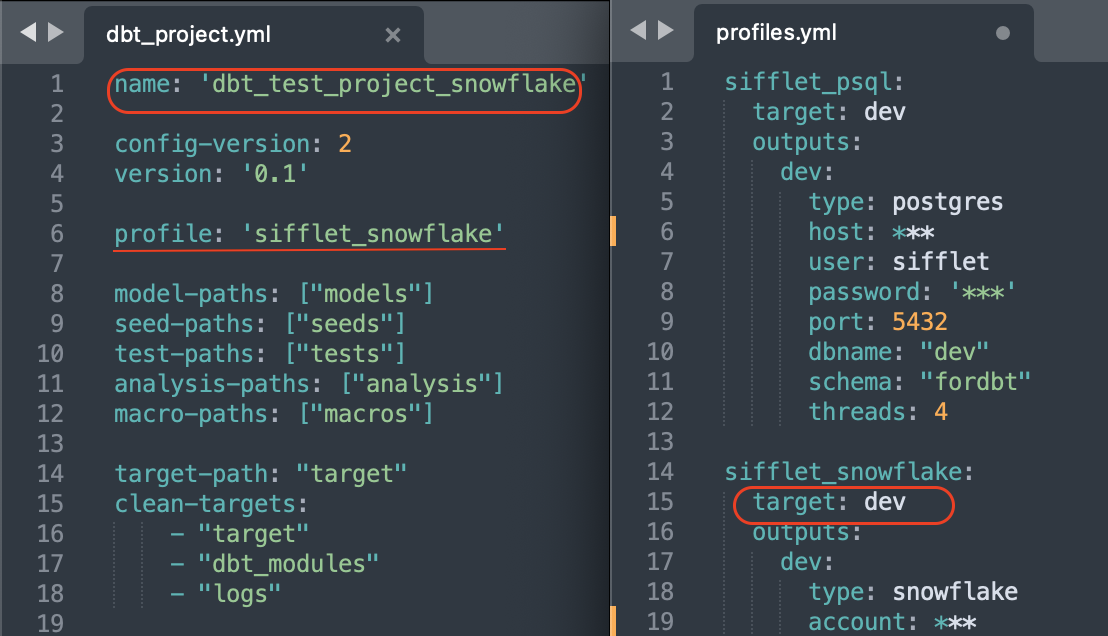
The profile is "sifflet_snowflake", hence the target is dev
-
(Optional) In Data pipeline failure notifications, select the Slack channels, Microsoft Teams channels, email addresses, or webhooks to notify when a model or seed run fails. See Pipeline Alerting.
-
Save the source.
The dbt Core source has no schedule and no Test Connection button: Sifflet ingests the artifacts each time your pipeline uploads them (step 2).
Step 2: Send the dbt Artifacts From Your Pipeline
After every dbt command that runs models or tests (dbt build, dbt run, dbt test), add a step that uploads the content of the dbt target/ folder to Sifflet. dbt overwrites run_results.json at each command, even when the command runs only a selection of models: if you upload only after the last command, Sifflet misses the results of the previous ones.
For example, a pipeline that runs models and tests separately:
dbt run --select model_1- Send the artifacts to Sifflet (status of
model_1). dbt run --select model_2 model_3- Send the artifacts to Sifflet (status of
model_2andmodel_3). dbt test- Send the artifacts to Sifflet (test results).
With a single dbt build, one upload after the command is enough.
Which artifacts to send:
run_results.json: after every command. Sifflet ingests all therun_results.jsonfiles uploaded since its previous ingestion.manifest.json: at least once, and again whenever your project changes (new models, tests, or descriptions). Sifflet uses the most recent one. Sending it with every upload is the simplest option.
Use one of the following methods. All of them need the project name and target of step 1, and the access token.
Option 1: Sifflet CLI
Install and configure the Sifflet CLI with your tenant and access token, then run after each dbt command:
sifflet ingest dbt --project-name <DBT_PROJECT_NAME> --target <DBT_TARGET> --input-folder <DBT_PROJECT_DIR>| Parameter | Required | Description | Example |
|---|---|---|---|
--project-name | Yes | Project name, as in the dbt Core source | analytics |
--target | Yes | Target, as in the dbt Core source | prod |
--input-folder | Yes | Path to the dbt project folder, which contains the target/ folder with the artifacts | /opt/dbt/analytics |
The CLI uploads the manifest.json, run_results.json, and catalog.json files it finds in <DBT_PROJECT_DIR>/target/. See the sifflet ingest dbt reference.
Option 2: Airflow Operator
If you orchestrate dbt with Airflow, add a SiffletDbtIngestOperator task after each dbt task. The operator is part of the Sifflet Airflow provider: see Airflow Custom Operators for its installation and the Airflow connection that holds the access token.
sifflet_dbt_ingest = SiffletDbtIngestOperator(
    task_id="sifflet_dbt_ingest",
    input_folder="<DBT_PROJECT_DIR>",
    target="<DBT_TARGET>",
    project_name="<DBT_PROJECT_NAME>",
)| Parameter | Required | Description | Example |
|---|---|---|---|
task_id | Yes | Unique identifier of the Airflow task | sifflet_dbt_ingest |
input_folder | Yes | Path to the dbt project folder, which contains the target/ folder with the artifacts | /opt/dbt/analytics |
target | Yes | Target, as in the dbt Core source | prod |
project_name | Yes | Project name, as in the dbt Core source | analytics |
sifflet_conn_id | No | Airflow connection to Sifflet. Default: sifflet_default | sifflet_default |
By default, the operator runs even when the upstream dbt task fails (trigger rule all_done), so that Sifflet receives the results of failed runs.
Option 3: Sifflet API
Call the API directly, for example with curl, from the dbt project folder:
#!/bin/bash

ACCESS_TOKEN="<SIFFLET_ACCESS_TOKEN>"
TENANT="<TENANT>"
PROJECT_NAME="<DBT_PROJECT_NAME>"
TARGET="<DBT_TARGET>"

curl --fail -X POST "https://${TENANT}.siffletdata.com/api/v1/metadata/dbt/${PROJECT_NAME}/${TARGET}" \
  -H "Authorization: Bearer ${ACCESS_TOKEN}" \
  -F "manifest=@target/manifest.json" \
-F "run_results=@target/run_results.json"| Parameter | Required | Description | Example |
|---|---|---|---|
ACCESS_TOKEN | Yes | The Sifflet access token of step 1. Read it from your secrets manager rather than writing it in the script | |
TENANT | Yes | Name of your Sifflet instance: if you access Sifflet at https://abcdef.siffletdata.com, the tenant is abcdef | abcdef |
PROJECT_NAME | Yes | Project name, as in the dbt Core source | analytics |
TARGET | Yes | Target, as in the dbt Core source | prod |
manifest | No | The manifest.json file | @target/manifest.json |
run_results | No | The run_results.json file | @target/run_results.json |
Sifflet answers 204 No Content when it accepts the artifacts.
What Happens Next
When it receives artifacts, Sifflet checks that they are valid dbt artifacts generated for the project and target of the source, stores them, and starts an ingestion of the dbt Core source. You can follow the ingestion in the source details, in Integrations > Sources. Once it succeeds, the dbt metadata appears on the asset pages of your models' tables and your dbt tests appear on the Monitors page. See dbt Collected Data.
Troubleshooting
The Upload of the Artifacts Fails
Symptom: the CLI, the operator, or the API call fails with one of the following errors:
No DBT datasource found for params ...
The uploaded dbt artifact "manifest.json" was generated by dbt project "...", but the dbt integration expects project "..."
The uploaded dbt artifact "run_results.json" was generated with dbt target "...", but the dbt integration expects target "..."
The uploaded dbt artifact "manifest.json" is not a valid JSON objectCause: no dbt Core source matches the project name and target of the upload, the artifacts were generated by another project or target, or a file is truncated or isn't a dbt artifact.
Fix:
- Check that the project name and target of the upload exactly match those of the dbt Core source, including case. See Create the dbt Core Source.
- Check that your pipeline runs dbt with the same target as the one you upload for (
--targetoption or default target ofprofiles.yml). - Check that you upload the files of the
target/folder produced by the dbt command that just ran.
dbt Tests or Models Show No Status or Last Run Information
Symptom: dbt tests on the Monitors page, or models in the catalog, have no status or last run date, or the status is outdated.
Cause: Sifflet didn't receive the run_results.json file produced by the command that ran them, usually because the pipeline only uploads the artifacts after its last dbt command.
Fix:
- Add an upload step after every
dbt build,dbt run, anddbt testcommand of your pipeline. See Step 2. - Check in the source details that the ingestion that followed the upload succeeded.
Updated 2 days ago